

Loading
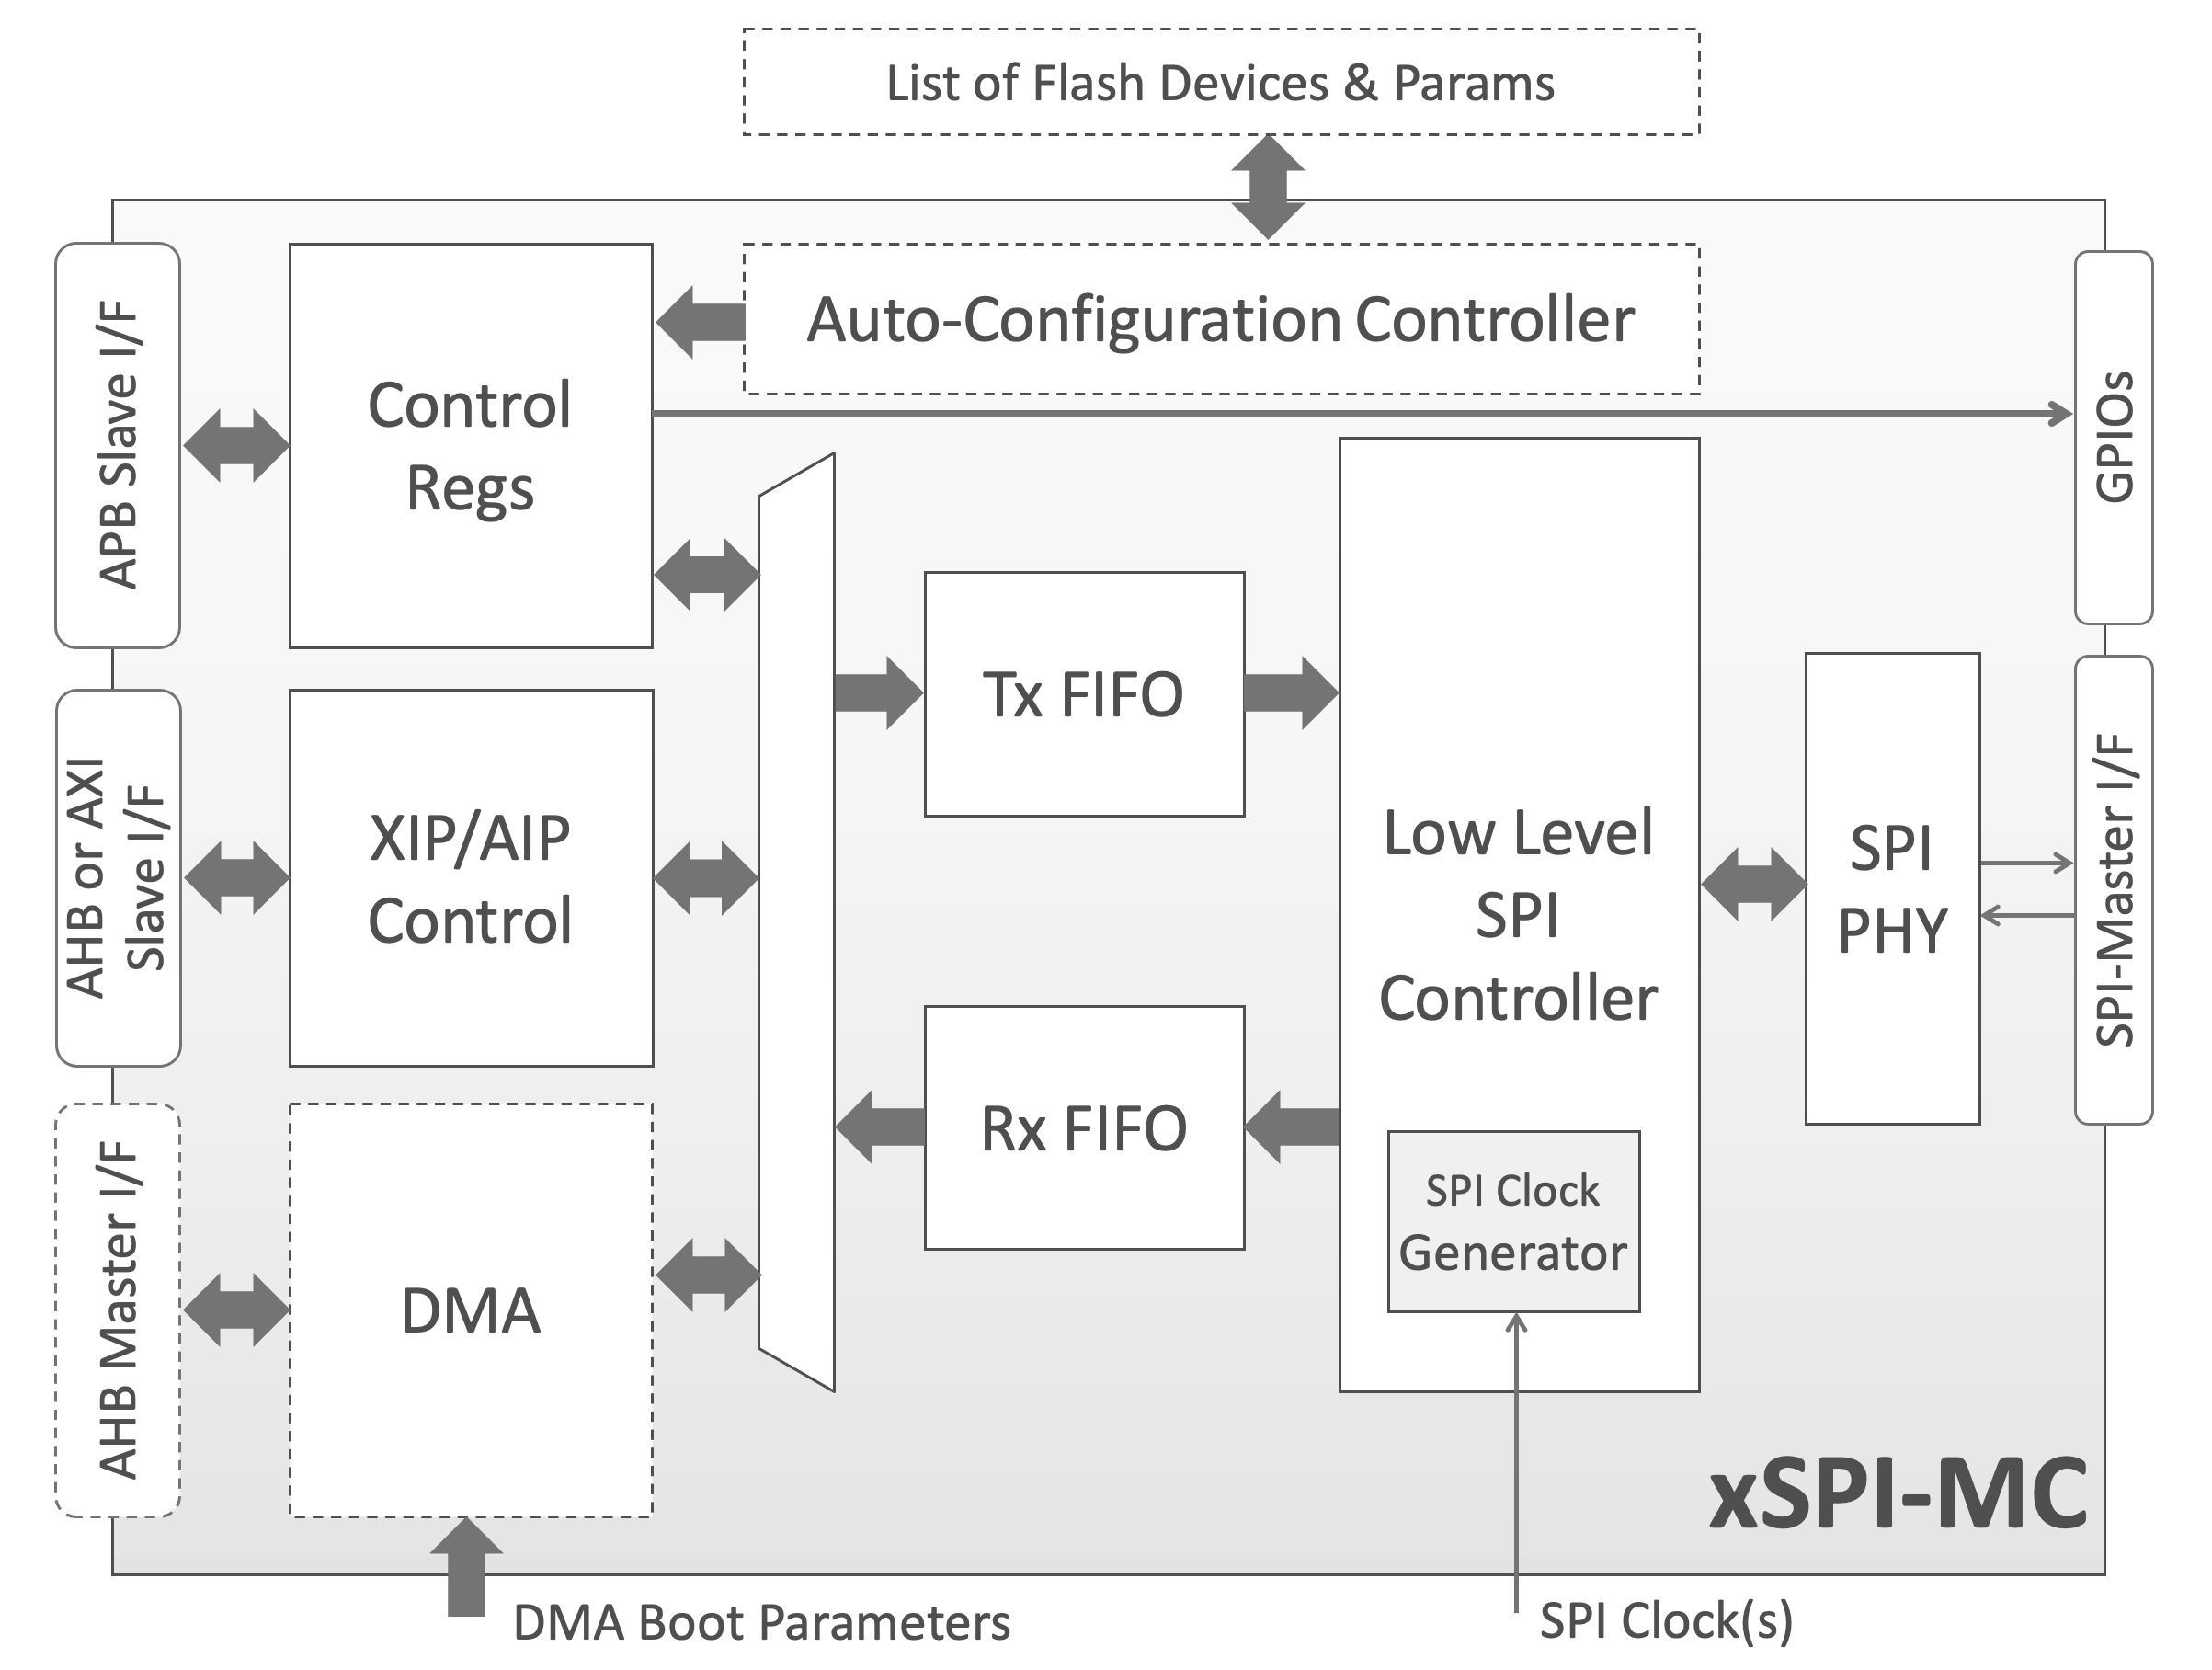
xSPI-MC: xSPI, HyperBus™, and Xccela™ Serial Memory Controller
The xSPI-MC is a versatile memory controller supporting JEDEC xSPI, HyperBus™, and Xccela™ standards, as well as proprietary SPI protocols for Flash and PSRAM. It enables easy device detection, direct boot, and operation in multiple modes: Slave (AHB slave access), DMA (with internal DMA engine), Access In-Place (AIP) via AHB/AXI, and Boot-Image copy after reset. Compatible with single to 16x SPI devices, it offers flexible configuration through registers or an auto-configuration feature using a device list. Highly customizable via Verilog defines, it allows selection of DMA, auto-configuration, and device count. Delivered with a synthesizable soft-PHY, it is FPGA/ASIC ready and requires no process-specific dependencies.
By Computer Aided Software Technologies, Inc (dba CAST)


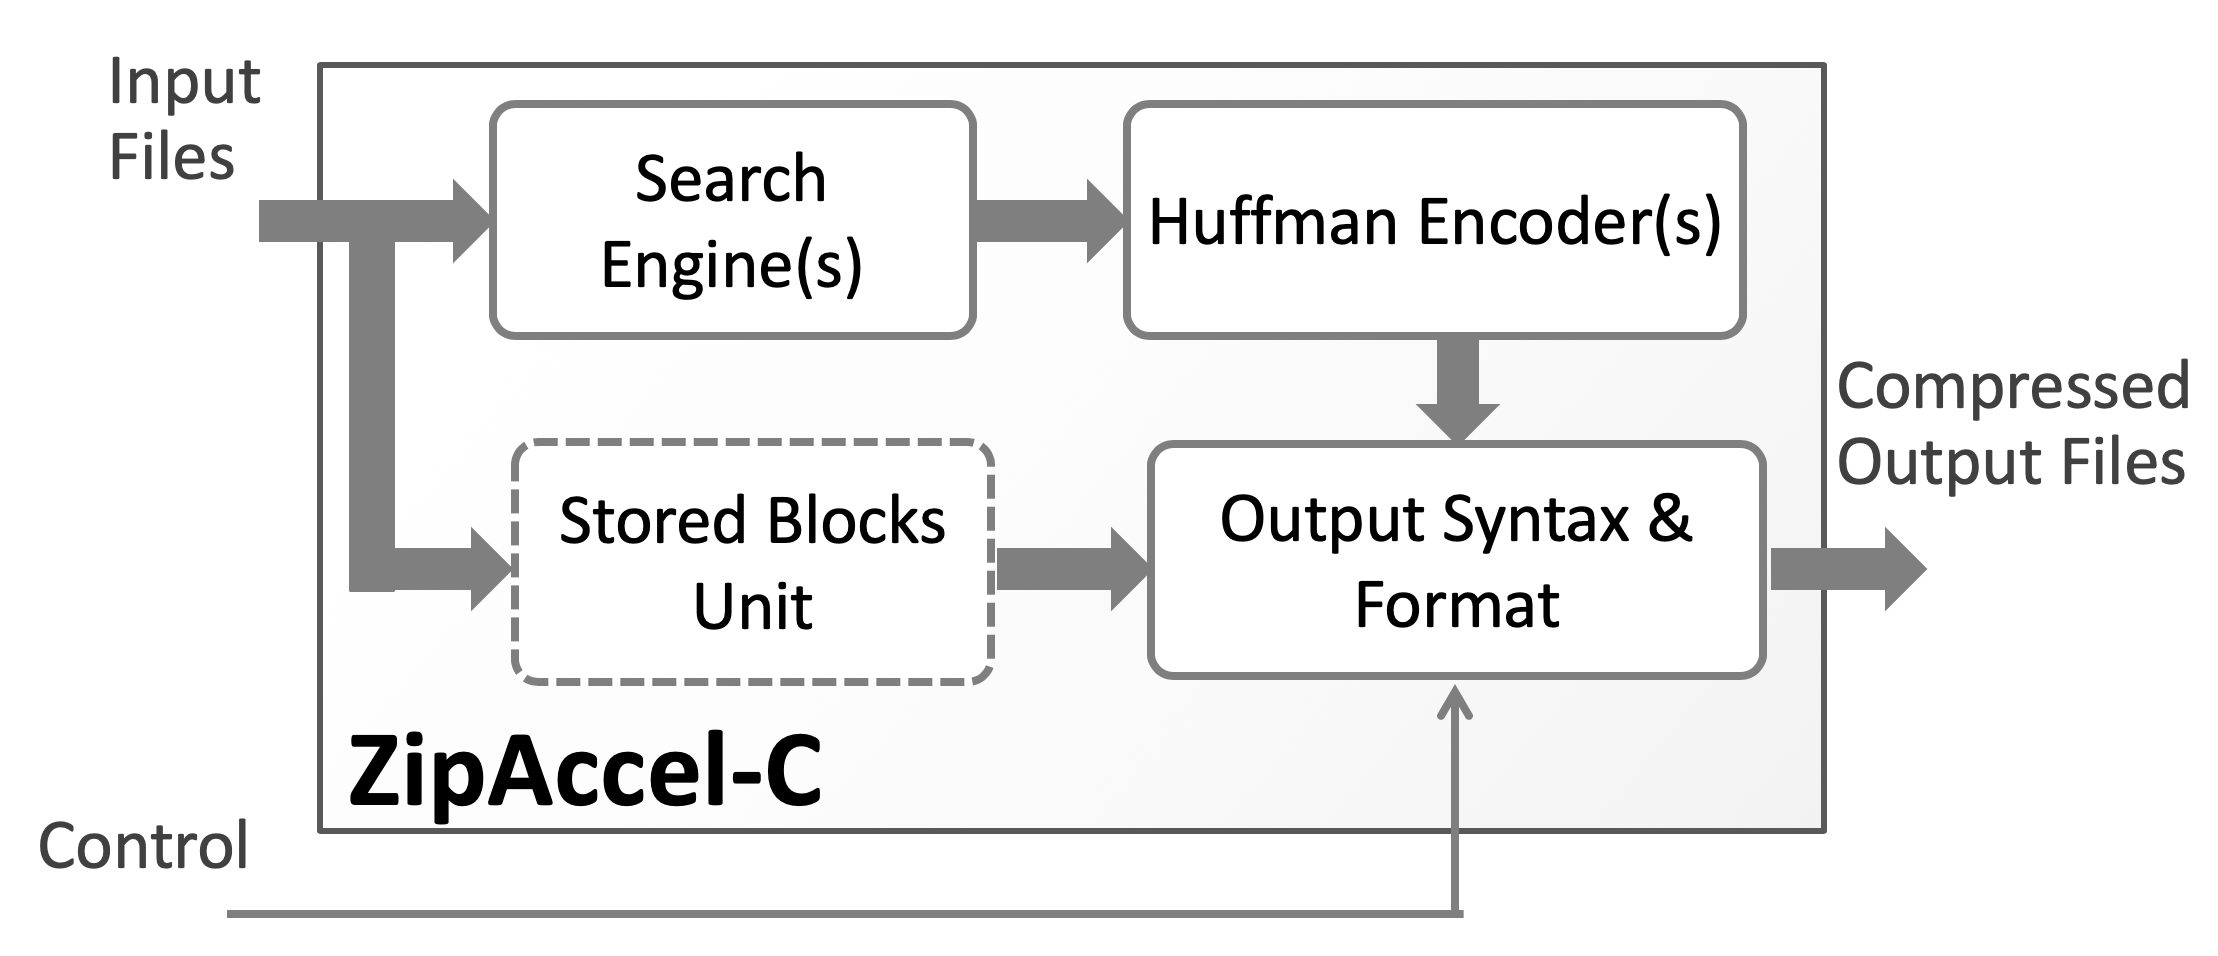
ZipAccel-C: GZIP/ZLIB/Deflate Data Compression Core
ZipAccel-C is a custom hardware implementation of a lossless data compression engine that complies with the Deflate, GZIP, and ZLIB compression standards.The core receives uncompressed input files and produces compressed files. No post-processing of the compressed files is required, as the core encapsulates the compressed data payload with the proper headers and footers. Input files can be segmented, and segments from different files can be interleaved at the core’s input.The core’s flexible architecture enables fine-tuning of its compression efficiency, throughput, and latency to match the requirements of the end application.
By Computer Aided Software Technologies, Inc (dba CAST)
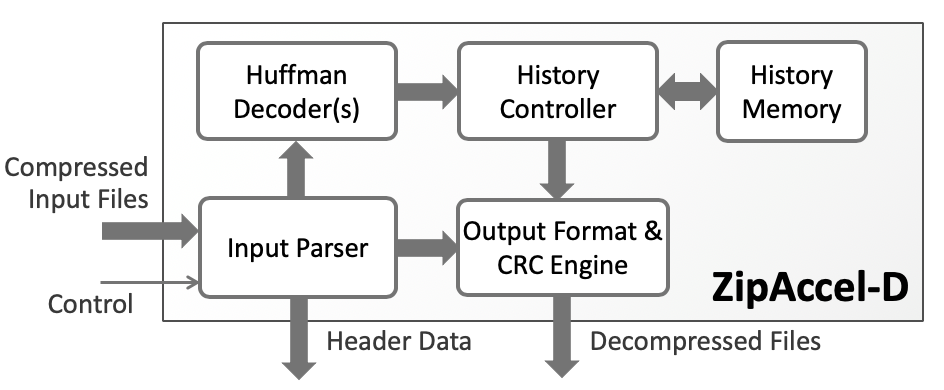
ZipAccel-D: GUNZIP/ZLIB/Inflate Data Decompression Core
ZipAccel-D is a custom hardware implementation of a lossless data decompression engine that complies with the Inflate/Deflate, GZIP/GUNZIP, and ZLIB compression standards.The core features fast processing, with low latency and high throughput. On average the core outputs three bytes of decompressed data per clock cycle. Designers can scale the throughput further by instantiating the core multiple times to achieve throughput rates exceeding 100Gbps. The latency is in the order of a few tens of clock cycles for blocks coded with static Huffman tables, and typically less than 2,000 cycles for blocks encoded with dynamic Huffman tables.
By Computer Aided Software Technologies, Inc (dba CAST)
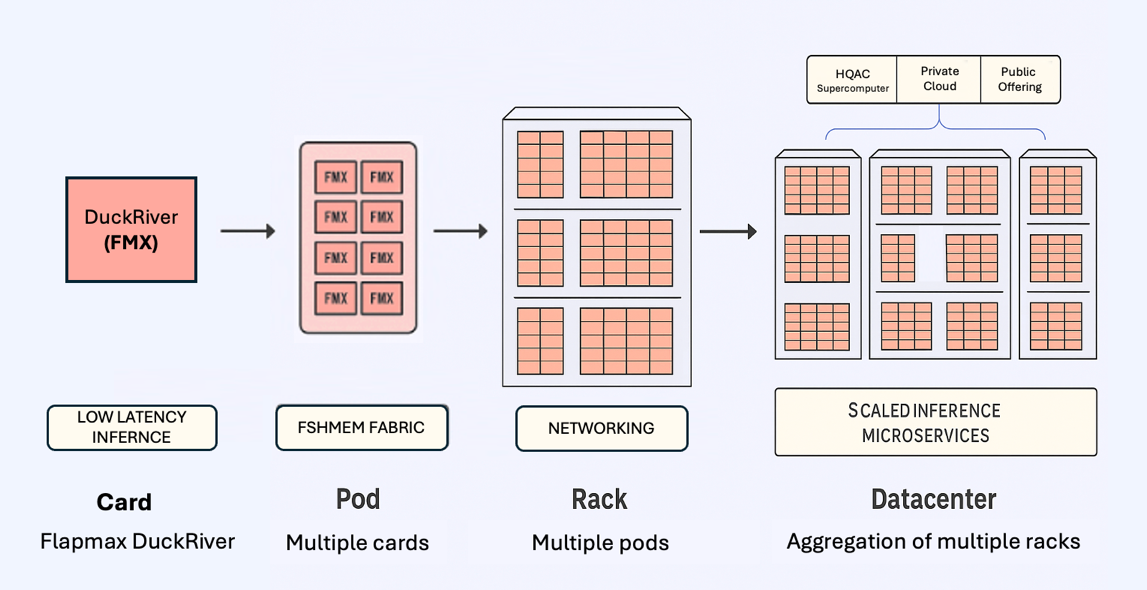
⚡Flapmax FMAX Inference
Sovereign AI inference engine scaling from server to datacenter for low-latency, energy-efficient performance.
By Flapmax
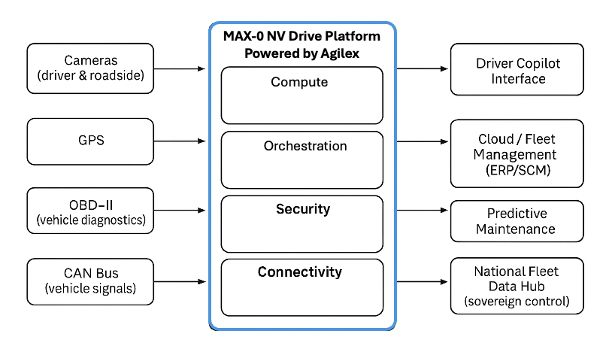
🚙 Flapmax NV Drive Platform
Neuromobility vehicle (NV) platform integrating AI retrofits, fleet intelligence, and national transport resilience.
By Flapmax