


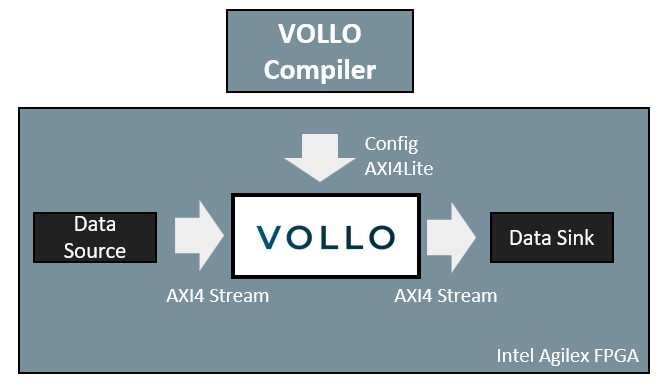
Lowest latency machine learning inference accelerator. Outperforms GPUs where latencies of tens of microseconds or less are required. SDK enables ML developers to compile their models and run them on VOLLO directly from PyTorch or TensorFlow and without requiring any FPGA expertise or tools. For those who do have FPGA expertise and tools, an FPGA netlist version is also available.

myrtle.ai


Key Features


Offering Brief
Offering Brief
| Device Family | Agilex® 7 FPGA F-Series |
|---|---|
| Offering Status | Production |
| Demo | Yes |
SDK includes all IP and tools to compile and run models on VOLLO, whether targeting supported FPGA-based PCIe accelerator cards or SmartNICs, or stand-alone FPGAs.
Documentation & Resources

Market Segment and Sub-Segments

Data Center Cloud (Public, Private, Hybrid)
View Sub-Segments
Defense
View Sub-Segments